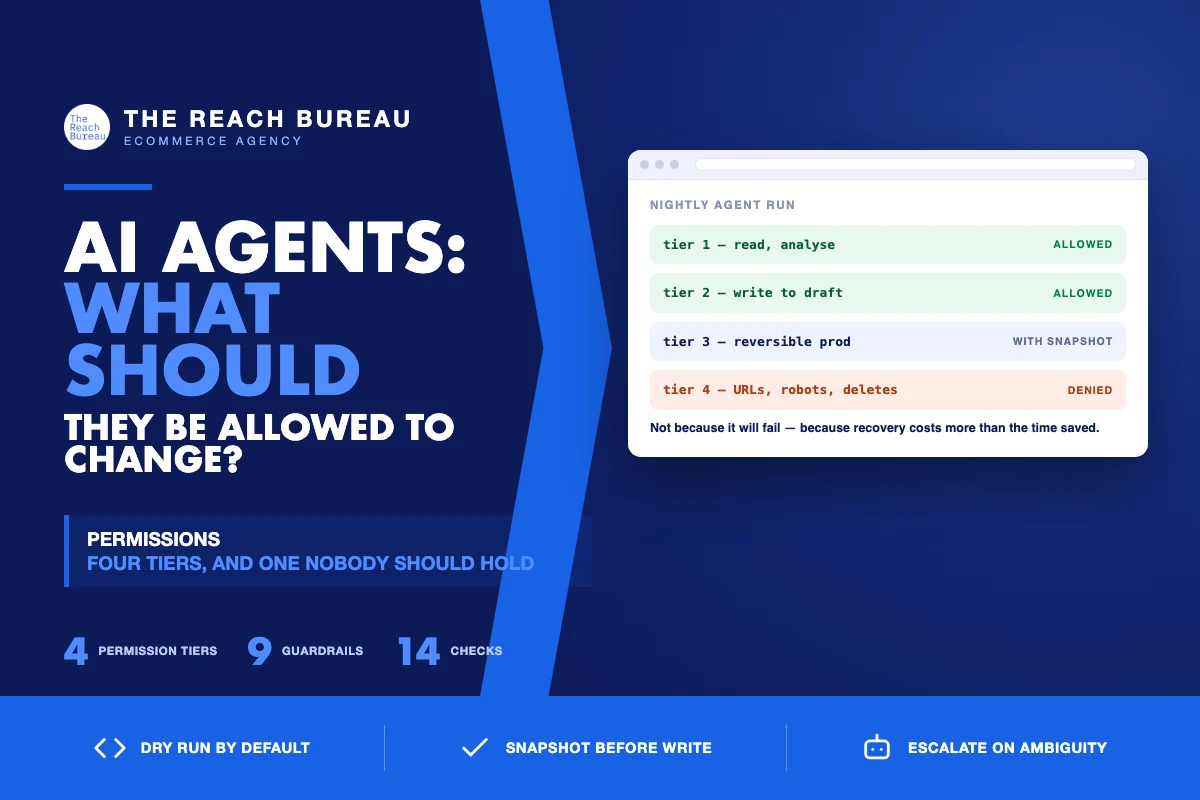
An assistant that suggests a change and an agent that makes one are different products with the same marketing. The first is a research tool. The second has write access to your store, and the interesting question about it is not what it can do — it is what it should be permitted to do, and what happens when it is wrong at three in the morning.
That question has an answer, and it looks like the permission model you would design for a new contractor rather than anything specific to AI.
The four permission tiers
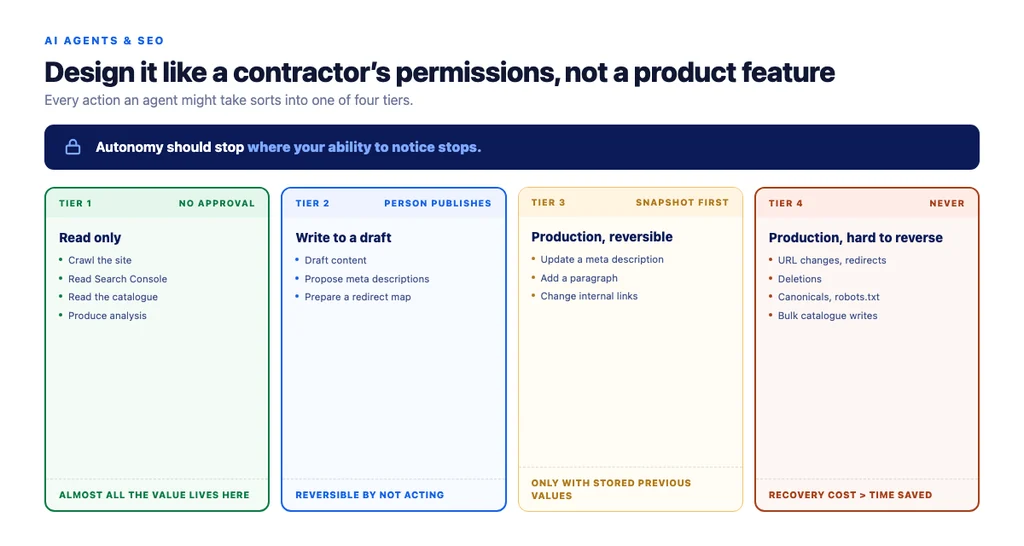
Sort every action an agent might take into one of these. The tier decides the guardrails.
Tier 1 — Read only. Crawl the site, read Search Console, read the catalogue, produce analysis. No write access anywhere. Almost everything valuable an agent does lives here, and this tier needs no approval process at all.
Tier 2 — Write to a draft. Generate content, propose meta descriptions, prepare a redirect map — into a draft state a person publishes. Reversible by not acting.
Tier 3 — Write to production, reversible. Update a meta description, add a paragraph, change internal links. Recoverable if you kept the previous value.
Tier 4 — Write to production, hard to reverse. URL changes, redirects, page deletion, canonical changes, robots.txt edits, bulk catalogue updates. An agent should not hold this tier. Not because it will necessarily fail, but because the recovery cost is disproportionate to the time saved.
The useful rule: an agent's autonomy should stop where your ability to notice stops. If nobody would spot the mistake within a day, the agent should not be making that change unattended.
What actually goes wrong
Not dramatic failures. Quiet, plausible ones.
- Confident wrong facts. An agent enriching product data invents a dimension. It reads exactly like a correct dimension.
- Rule generalisation. A pattern learned from standard products applied to bundles, made-to-order items and variants.
- Cascading edits. One change triggers a template rebuild that touches four hundred pages.
- Silent no-ops. The job reports success and changed nothing, for months.
- Context loss between runs. The agent does not remember why a human overrode it last week and helpfully undoes the override.
- Optimising the measurable. Told to improve click-through rate, it writes titles that overpromise, which raises CTR and returns.
None of these is exotic. All of them are what happens when a competent process runs without someone checking the output.
Guardrails that make autonomy survivable
1. Dry run by default. The agent produces a diff; nothing is applied without an explicit apply step. 2. A readable diff. Values, not row counts. "412 rows updated" is not a diff. 3. Blast radius cap. Refuse to change more than N items per run without confirmation. Pick N as the number you would actually review. 4. Snapshot before write. Previous values stored, restorable. On a catalogue this means real data, not "we could regenerate it". 5. A deny list of fields. Price, stock, URL, canonical, robots directives, structured data — an agent does not touch these unattended, whatever the task. 6. Output assertions. Did the field change? If a run legitimately changes nothing, that is worth reporting too. 7. A single audit log. Every action, timestamped, attributable, readable by a human who was not there. 8. A kill switch someone knows how to use — and has used once, deliberately, to check it works. 9. Escalation on ambiguity. The agent stops and asks rather than choosing when a rule does not clearly apply.
Number 4 is the one that turns an incident into an inconvenience. Number 9 is the one that separates a well-designed agent from an enthusiastic one.
Where agents are genuinely useful now
Monitoring and diagnosis. Watch the crawl, the index count, structured data validity, and report anomalies with context. Read-only, high value, no risk.
Preparing work. Draft the redirect map, the meta descriptions, the attribute completions — as a reviewable artefact.
Cross-referencing. Joining Search Console data to catalogue data to revenue data is tedious, mechanical and exactly what this is good at.
Explaining. What changed on this page, when, and what it correlated with.
Bulk classification. Page types, intent groupings, attribute normalisation.
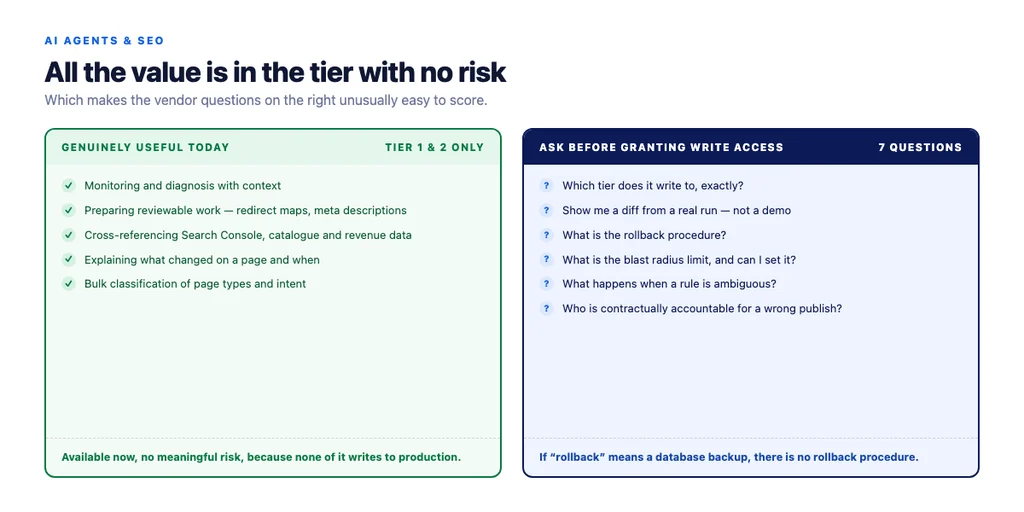
Notice all of it is Tier 1 and Tier 2. That is where the value is, and it is also where the risk is not.
Questions to ask a vendor
- Which tier does it write to, exactly? A straight answer here tells you most of what you need.
- Show me a diff from a real run. Not a demo. A diff.
- What is the rollback procedure? If the answer involves a database backup, there is no rollback procedure.
- What is the blast radius limit, and can I set it?
- What does the audit log contain?
- What happens when the rule is ambiguous? "It uses judgement" is the wrong answer.
- Who is accountable when it publishes something wrong? Contractually, not conversationally.
If a vendor cannot answer the first and third, the product is not ready for write access to a store that takes money.
The honest position
Agents do compress real work — the monitoring, the preparation, the cross-referencing. That is worth having and it is available today with no meaningful risk, because it is all read-only.
The write-access story is less mature than it is marketed. The constraint is not model capability; it is that ecommerce catalogues are full of edge cases, the failures are quiet, and the recovery costs are asymmetric. Keeping an agent in Tiers 1 and 2 gets you most of the benefit and none of the incidents — and that will remain the sensible default until the tooling around agents is as good as the agents.
The checklist
- Every agent action classified into a permission tier
- No agent holds Tier 4 access
- Autonomy stops where your ability to notice stops
- Dry run is the default, apply is explicit
- Diffs show values, not counts
- Blast radius capped at a number you would review
- Previous values snapshotted and restorable
- Deny list covers price, stock, URLs, canonicals, robots, structured data
- Output assertions catch silent no-ops
- Single readable audit log
- Kill switch tested once, deliberately
- Agent escalates on ambiguity rather than choosing
- Human overrides recorded so they survive the next run
- Vendor questions answered before write access granted
Sources
- Google Search Essentials — Google Search Central
- Google Search and AI-Generated Content — Google Search Central Blog
- SEO Best Practices for Ecommerce Sites — Google Search Central
- Spam Policies for Google Web Search — Google Search Central
- Intro to Product Structured Data on Google — Google Search Central
Frequently Asked Questions
Want this run against your store? Book a call with The Reach Bureau.